What is a superforecaster? Who they are and how to become one
Superforecasters are the top forecasters from a US intelligence tournament. Who they are, what makes them accurate, and how to become one.
Read the article
A calibrated forecaster's 70% calls come true about 70% of the time. What calibration means, how to check it, and why people and AI are often overconfident.
 By Kristian FagerlieFounder & CEO, Sikt Intelligence
A forecaster is calibrated when their probabilities match how often things actually happen. Of all the events they call at 70%, about 70% should happen. Of all the events they call at 10%, about one in ten should happen. It is the single most important property a probability can have, because it is what makes the number mean something.
You already rely on calibration every day. When a weather app says "70% chance of rain", you trust that on days like this it rains about seven times out of ten. That trust was earned: weather forecasters were shown decades ago to give reliable probabilities (Murphy and Winkler, 1977).
A single forecast can never be right or wrong. If you say 70% and the event does not happen, you have not failed. A 70% forecast expects to miss three times out of ten.
That is why calibration is always judged across many forecasts. One call tells you nothing. A hundred calls tell you whether the numbers keep their promise.
A probability is a promise about frequency. Calibration is whether the promise is kept.
Group forecasts by the probability that was given, then compare each group with what happened. The result is a reliability table, or drawn as a chart, a reliability diagram.
Here is what one looks like for a well-calibrated forecaster. The numbers are illustrative.
| Forecast given | Forecasts | Came true | Hit rate |
|---|---|---|---|
| 10% | 120 | 13 | 11% |
| 30% | 95 | 27 | 28% |
| 50% | 80 | 41 | 51% |
| 70% | 110 | 76 | 69% |
| 90% | 60 | 55 | 92% |
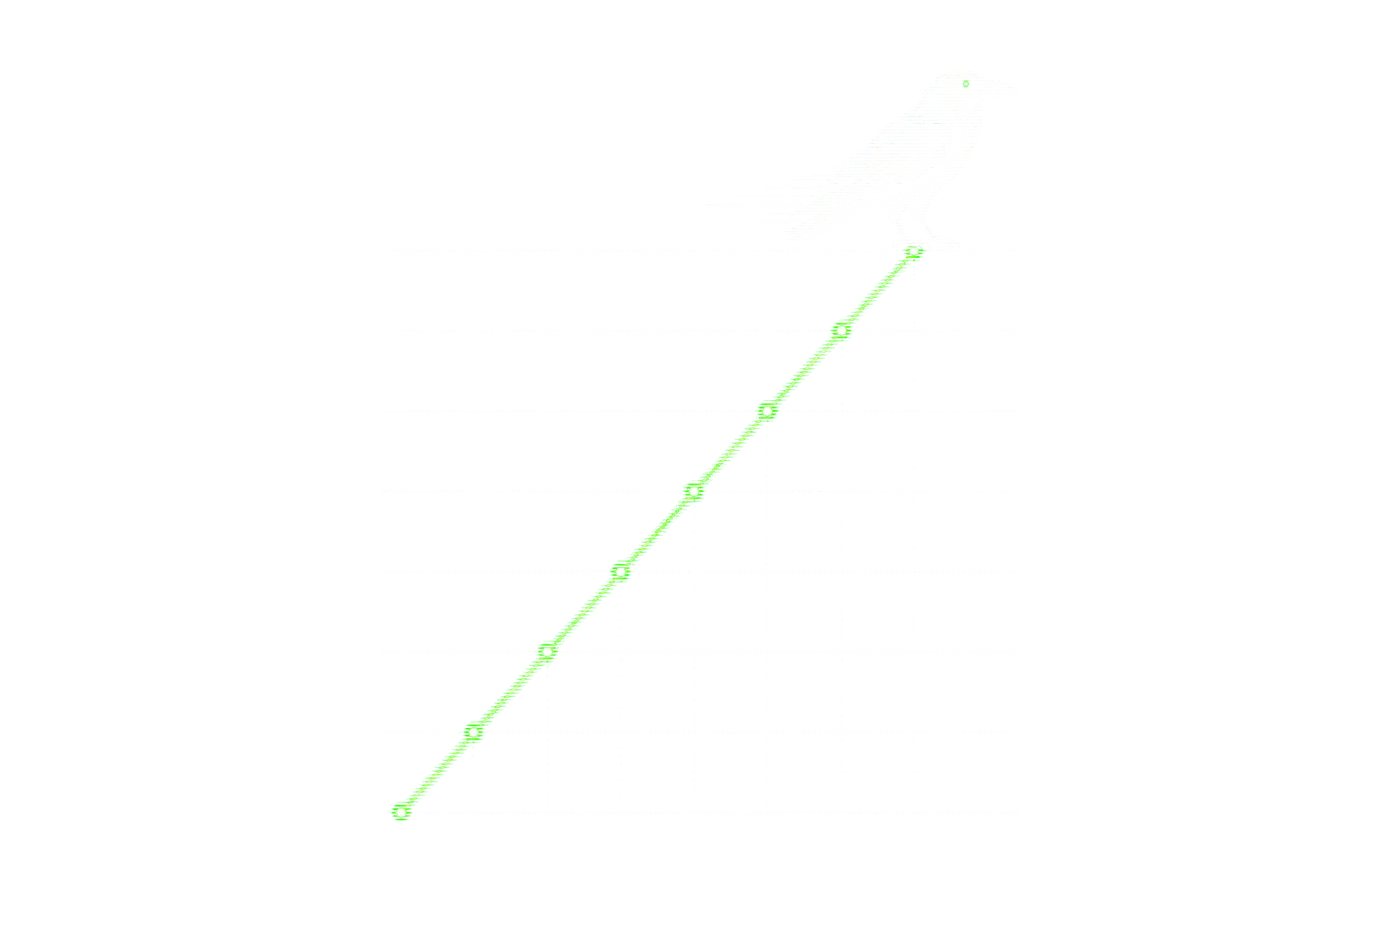
Each hit rate sits close to the forecast that was given. On a chart, the points would fall on the diagonal line from bottom left to top right, the line of perfect calibration.
A badly calibrated forecaster shows a pattern instead:
Two practical rules: you need volume, because with five forecasts in a group luck dominates; and you need honest records, logged before the answer is known, with the misses kept.
Decades of research find the same thing: people are overconfident. In a landmark review of calibration studies, people who gave ranges they were 98% sure contained the right answer were right only about 68% of the time, across nearly 15,000 judgments (Lichtenstein, Fischhoff and Phillips, 1982, as summarised by Scott Plous).
Confident language feels informative, so it gets used more than the evidence supports. Pundits make it worse: "it's definitely happening" implies 100%, but it is never written down, never checked, and never scored.
Language models share the problem, which is one reason the answer to can AI predict the future? depends so much on calibration. Their raw probabilities tend to sound surer than their record justifies, which is why serious AI superforecasters calibrate their output against a track record.
A forecaster who says 50% on every question can look reasonably calibrated and be useless. Good forecasts need two things:
The Brier score captures both. It rewards forecasters who are honest and decisive when the evidence allows. To check your own record, paste it into our free Brier score calculator: it shows your Brier score and a calibration table.
Prediction market prices are often read as probabilities, and on average they are fairly well calibrated (see how accurate are prediction markets?). But studies find systematic patterns at the extremes, such as the favorite-longshot bias, where cheap long-shot contracts win less often than their price implies. Knowing where a source is miscalibrated tells you where to be careful with it.
At Sikt Intelligence, calibration is the core promise: when Sikt says 70%, it should happen about 7 times out of 10. Every forecast is graded when it resolves, misses included, and the track record decides how much to trust it. We are in the research stage, so performance claims will come only from a published record. You can see the kind of questions we forecast in the predictions feed.
That across many forecasts, events given a probability of X% happen about X% of the time. A well-calibrated 70% comes true about 7 times in 10.
At least dozens per probability group, and ideally hundreds overall. With only a handful of forecasts, luck dominates the result.
Largely, yes. Research since the 1970s has found that weather forecasters give reliable probability forecasts, which is why a "70% chance of rain" is a number people can use.
Superforecasters are the top forecasters from a US intelligence tournament. Who they are, what makes them accurate, and how to become one.
Read the article
What the Brier score and Brier skill score mean: the formula, worked examples, what counts as a good score, and a free calculator for your own forecasts.
Read the article